Ordalin
Submit a tool

Website-checked tool profile

Fish Audio

Voice AI platform for expressive text-to-speech, voice cloning and transcription, with open-weight models and a pay-as-you-go API.

Sources checked

Visit website ↗
Pricing
The web app has a free tier with 8,000 credits a month, enough for about 7 minutes of speech, for personal non-commercial use only. Plus costs $15 a month ($11 a month billed annually) for 250,000 credits and commercial use. Pro costs $100 a month ($75 annually) for 2,000,000 credits and 3 team seats. Max costs $999 a month ($749 annually) for 25,000,000 credits. Enterprise is custom. The API is billed separately as pay-as-you-go: $15 per million UTF-8 bytes for s2.1-pro, a $0 s2.1-pro-free model under fair-use limits, and $0.36 per audio hour for transcription. Official source 1 ↗ · Official source 2 ↗
Available as
Web app with no code needed, a REST and WebSocket API, and official Python and TypeScript SDKs. A remote MCP server connects Claude, Cursor and other MCP clients. Enterprise customers can self-host the open-weight models. Official source 1 ↗ · Official source 2 ↗
Primary group
Voice & Speech

Also consider

See all 6 similar tools ↓

What it does

Fish Audio is a voice AI platform from Hanabi AI Inc. It covers text-to-speech with inline emotion and direction tags, instant voice cloning, voice design from a text prompt, speech-to-text, a voice changer and Story Studio for long-form multi-speaker audio. You can use each core feature in the no-code web app, through the REST API or with the official SDKs. Its fish-speech, S1 and S2 models are released as open weights, with a paid commercial licence.

Official source 1 ↗ · Official source 2 ↗

Features

  • Expressive text-to-speech with emotion tags. Control delivery with inline text markers. The docs list 64+ emotions and voice styles, and S2 models accept free-form bracket directions such as [whispers sweetly]. Official source 1 ↗ · Official source 2 ↗
  • Instant voice cloning. Clone a voice from a short clip, or train a persistent voice model. The homepage says 15 seconds of audio is enough. Official source 1 ↗ · Official source 2 ↗
  • Voice design from a description. Create an original voice from a plain-text description. Official source 1 ↗
  • Speech-to-text. transcribe-1-pro handles multi-speaker conversations, long recordings and emotion cues, with optional timestamps. Official source 1 ↗
  • Story Studio for long-form audio. Produce multi-speaker long-form audio, such as audiobooks and narration, in the browser. Official source 1 ↗
  • Voice changer, music, sound effects and stem separation. Web-app tools turn existing audio into another voice, generate music and sound effects from a prompt, and split audio into stems. Official source 1 ↗
  • Realtime streaming for voice agents. Stream audio while it generates over WebSocket, with streaming TTS and ASR for conversational agents. Official source 1 ↗
  • Multilingual voices. The homepage says any voice can speak 30+ languages, and the model docs list 83 languages for S2.1-Pro. Official source 1 ↗ · Official source 2 ↗
  • Large community voice library. Browse a voice library of 2M+ community voices. Official source 1 ↗
  • Open-weight models. fish-speech, S1 and S2 are released as open weights. Commercial use needs a paid licence. Official source 1 ↗

Pricing & free limits

Free

$0per month

8,000 credits a month (about 7 minutes), up to 500 characters per generation, 3 public voice slots, standard speed. Personal, non-commercial use only. Official source 1 ↗
Plus

$15per month, or $11/month billed annually ($132/year)

250,000 credits a month (up to 200 minutes), 15,000 characters per generation, unlimited public plus 10 private voice slots, Voice Design, 1 professional voice slot, commercial use. Official source 1 ↗

Pro

$100per month, or $75/month billed annually ($900/year)

2,000,000 credits a month (up to 1,620 minutes), 3 team seats, 30,000 characters per generation, unlimited voice slots, 5 professional voice slots, 7-day money-back guarantee. Official source 1 ↗

Max

$999per month, or $749/month billed annually ($8,988/year)

25,000,000 credits a month (up to 6,250 minutes), 10 team seats, 15 professional voice slots. Official source 1 ↗

Enterprise

Custombilled annually

Volume pricing with zero data retention, on-premise deployment and SOC 2 compliance. Official source 1 ↗

API (pay-as-you-go)

$15 per 1M UTF-8 bytesusage-based

s2.1-pro and s2-pro TTS cost $15 per million UTF-8 bytes, and s2.1-pro-free costs $0. Transcription costs $0.36 per audio hour, and voice design costs $0.01 per successful request. Official source 1 ↗

Billing details

One minute of generated speech uses about 600–625 credits. Credits reset each month and unused minutes do not roll over. Official source 1 ↗

The API is billed apart from the web-app plans, with no subscription fee or monthly minimum. One million UTF-8 bytes is about 12 hours of English speech. Official source 1 ↗

Free access & limits

The free tier gives 8,000 credits a month (about 7 minutes), caps each generation at 500 characters, includes 3 public voice slots and allows only personal, non-commercial use. On the API, s2.1-pro-free costs $0 under fair-use limits, with no TTFA or DPA guarantees. Official source 1 ↗ · Official source 2 ↗ · Official source 3 ↗

Best for & limitations

Creators producing voiceovers, audiobooks and podcasts in several languages. Official source 1 ↗

Developers building realtime voice agents and AI avatar products over the API. Official source 1 ↗

Teams that need to run the model in their own VPC, on-prem or air-gapped. Official source 1 ↗
  • Free output is personal use only. Commercial use and monetisation, such as on YouTube or podcasts, need a paid plan. Official source 1 ↗
  • Open weights are not free for commercial use. The open-source models need a paid commercial licence, and self-hosting is sold as an Enterprise engagement. Official source 1 ↗
  • S1 model retires at the end of 2026. Requests to the deprecated S1 model will be served and billed as s2.1-pro after December 31, 2026. Official source 1 ↗
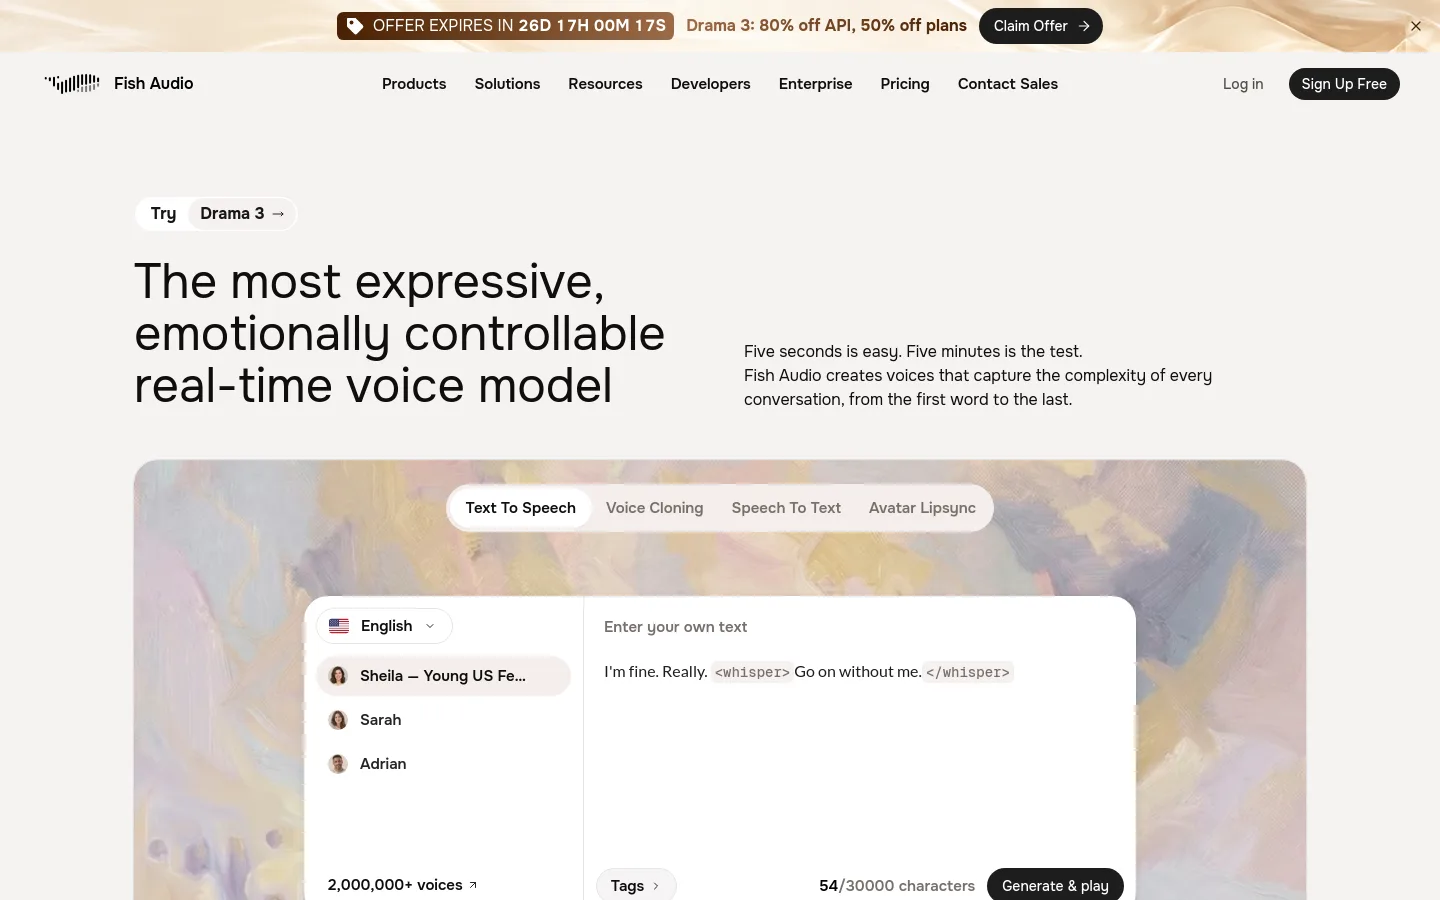
Fish Audio product screenshot
Website previewFixed desktop viewport · 1440 × 900

Similar tools

Published tools that share its categories.
VoxCPMOpen-source multilingual text-to-speech model from OpenBMB with voice design, voice cloning and 48kHz output.
Voice & SpeechFreeChecked Oct 14
Visit
OnepinAI voice production agent that routes scripts across 30+ TTS models, validates every line and auto-fixes misreads.
Voice & SpeechFree planChecked Oct 11
Visit