Ordalin
Submit a tool

Reviewed tool profile

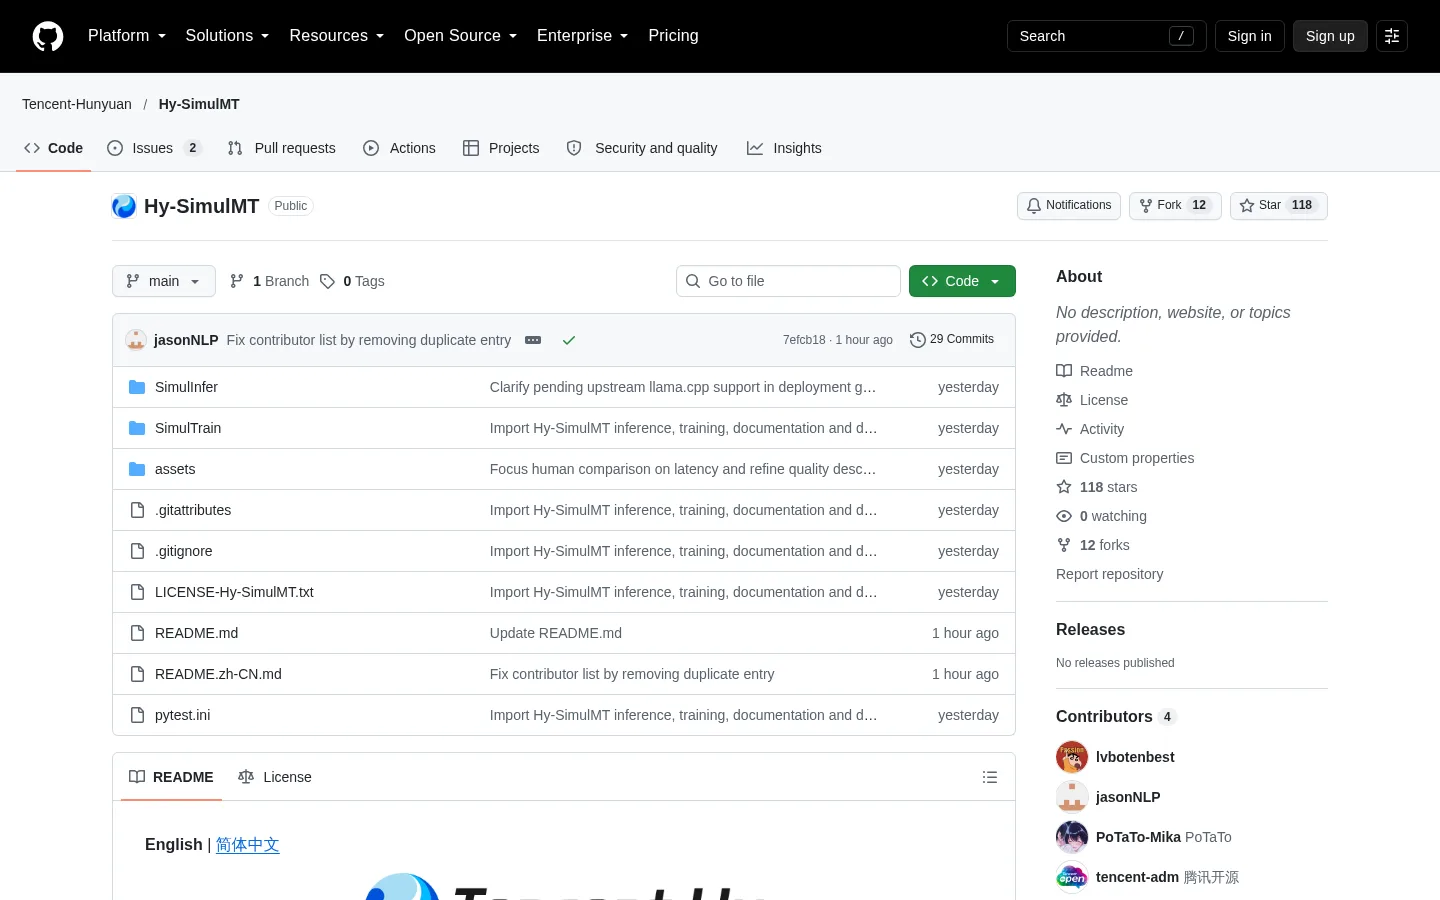
Hy-SimulMT

Tencent Hunyuan's open-weight model for real-time Chinese–English simultaneous interpretation with voice cloning.

Sources checked

Visit website ↗
Pricing
The model weights are free to download from Hugging Face and ModelScope, and the SimulInfer inference service is in the GitHub repository. You run it on your own Linux machine with an NVIDIA GPU. No paid hosted API is published; Tencent's Hy Translate app is the hosted way to try it. Official source 1 ↗
Available as
Self-hosted on Linux with Python 3.12+ and an NVIDIA GPU, served through vLLM (0.31 or later) with the SimulInfer web page and API. · Hy Translate app for Android and iOS. Official source 1 ↗ Official source 1 ↗
Primary group
Writing & Language

Also consider

See all 6 similar tools ↓

What it does

Hy-SimulMT is Tencent Hunyuan's real-time simultaneous translation model, released on 26 October 2026. It listens to a continuous audio stream and translates Chinese speech into English, or English into Chinese, while the speaker is still talking, producing translated text and, with a TTS service connected, translated speech in a clone of the speaker's voice. The weights are published on Hugging Face and ModelScope, the GitHub repository adds the SimulInfer inference service and SimulTrain training tools, and Tencent's Hy Translate app offers it without self-hosting.

Official source 1 ↗

Features

  • Simultaneous Chinese–English translation. Translates in both directions, Chinese to English and English to Chinese, as the audio arrives instead of waiting for the speaker to finish. Official source 1 ↗ · Official source 2 ↗
  • Low lag on long talks. On Tencent's RealSI long-form benchmark it lagged the speaker by about 3 seconds (StreamLAAL), the lowest of the systems Tencent compared, while scoring above the compared open models and four of five commercial APIs on translation quality. Official source 1 ↗
  • Real-time voice cloning. With a TTS service connected, the translated speech keeps the original speaker's vocal characteristics, so listeners can tell multiple speakers apart. Official source 1 ↗
  • Translation-only or source-plus-translation output. Six checkpoints: the base model outputs only the translation, the Interleave model also shows the source transcript, and each comes in FP8 and GGUF versions. Official source 1 ↗
  • Web page, file upload and WebSocket API. SimulInfer serves a browser page, audio file uploads and a real-time WebSocket, and one deploy.sh command installs dependencies, starts vLLM and starts the web/API service. Official source 1 ↗
  • Noise-resistant mode and chunk sizes. A noise-resistant audio mode targets noisy rooms, voice activity detection can be switched on or off, and a short-chunk mode uses 800 ms chunks after the first 1,600 ms chunk instead of the recommended 1,600 ms standard mode. Official source 1 ↗
  • Training tools included. The repository also ships SimulTrain training tools alongside the inference service. Official source 1 ↗

Pricing & free limits

Open weights (self-hosted)

$0Self-hosted

Download the six checkpoints from Hugging Face or ModelScope and run SimulInfer on your own Linux machine with an NVIDIA GPU. Speech output and voice cloning need a separate TTS service. Official source 1 ↗
Hy Translate app

Not publishedMobile app

Tencent's Android and iOS app lets you try Hy-SimulMT without running it yourself; the repository does not state its price. Official source 1 ↗

Billing details

Billing details were not established by the checked official sources.

Free access & limits

Free access and its limits were not established by the checked official sources.

Best for & limitations

Following a speech, interview or meeting in the other language with about a 3-second lag, in Chinese–English settings. Official source 1 ↗

Live dubbing of a multi-speaker interview where each speaker keeps a recognisable voice in the translation. Official source 1 ↗

Translating uploaded recordings or a live microphone feed from your own server, through the SimulInfer web page or its WebSocket API. Official source 1 ↗ · Official source 2 ↗
  • Chinese and English only. Simultaneous speech translation covers Chinese to English and English to Chinese only. Official source 1 ↗
  • Needs your own GPU and a TTS service. Self-hosting requires Linux and an NVIDIA GPU with enough memory for the model; translated speech and voice cloning only work after you connect a separate TTS service. Official source 1 ↗
  • Benchmarks are Tencent's own. The latency and human-interpreter comparisons come from Tencent's tests on 18 recordings, and Tencent says they do not assess speech quality or voice similarity. Official source 1 ↗
  • Low-risk settings first. Tencent positions it for low-risk settings and says professional interpreters remain important where accountability or high-stakes decisions are involved. Official source 1 ↗
Hy-SimulMT product screenshot
Website previewFixed desktop viewport · 1440 × 900

Similar tools

Published tools that share its categories.
TypelessAI voice dictation that turns rambling speech into clean, formatted text in any app on desktop and mobile.
Voice & SpeechFree planChecked Oct 31
Visit
Doc2XParse PDFs and scans into Word, Markdown, LaTeX or Excel with formulas and tables intact, and translate them with your choice of LLM.
Research & DataFree planChecked Oct 17
Visit
SpeakONAI dictation for iPhone with a MagSafe button: press, speak, and polished text lands in any app.
Voice & SpeechFree planChecked Oct 10
Visit
SoniloAI music and sound effects generated from a video or a text prompt and timed to the footage, with video translation and dubbing, a web app and a developer API.
Music & AudioFree planChecked Oct 6
Visit