Ordalin
Submit a tool

Reviewed tool profile

Ripple-65B Preview

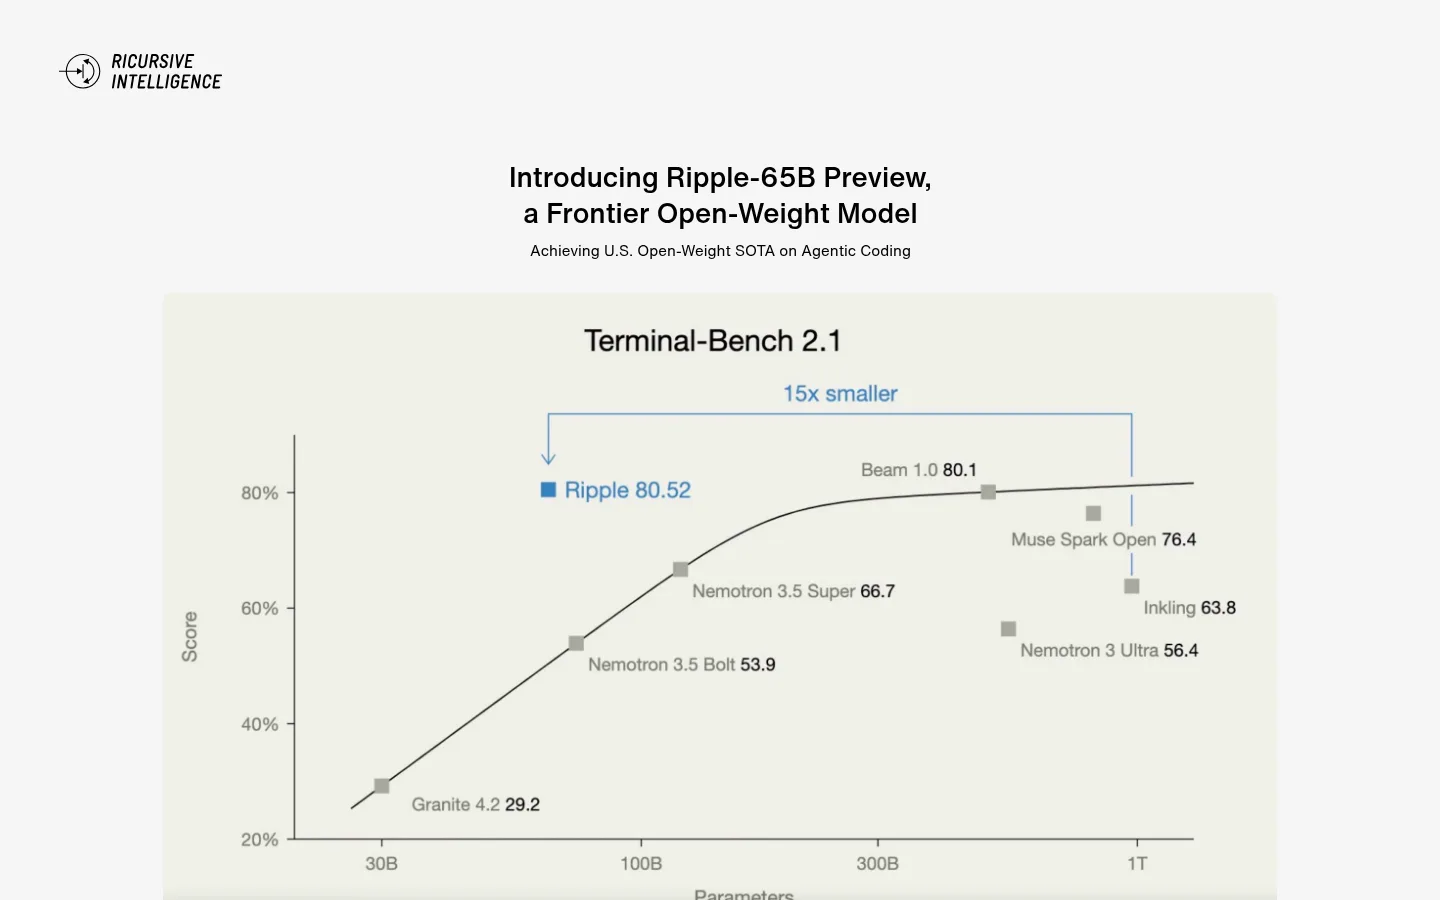
Ricursive Intelligence's 65B dense open-weight model for agentic coding, scoring 80.5 on Terminal-Bench 2.1.

Sources checked

Visit website ↗
Pricing
The weights are free to download from Hugging Face under the Apache License 2.0, so self-hosting costs only your own hardware. Ricursive does not sell its own API; hosted access goes through Together AI, GMI Cloud, OpenRouter and Fireworks, which set their own prices (not stated on Ricursive's pages). Official source 1 ↗ · Official source 2 ↗
Available as
Self-hosted from the Hugging Face weights: BF16 and a conservative NVFP4 quantization (NVFP4 MLP layers, BF16 attention), which Ricursive says fits on an NVIDIA DGX Spark, with a Colab to get started. · Datacenter serving with the bundled SGLang 0.5.19 launcher on two NVIDIA B200 GPUs (Linux, CUDA Toolkit 13), exposing an OpenAI-style chat completions endpoint with tool calls. · Hosted APIs from Together AI, GMI Cloud, OpenRouter and Fireworks. Official source 1 ↗ · Official source 2 ↗ Official source 1 ↗ Official source 1 ↗
Primary group
Coding & Development

Also consider

See all 6 similar tools ↓

What it does

Ripple-65B Preview is the first language model from Ricursive Intelligence, a lab working on AI for chip design. It is a 65-billion-parameter dense Transformer trained from scratch on 12 trillion tokens, with up to 1M tokens of context, and a general-purpose variant of the model behind Ricursive's own chip design platform. Ricursive reports 80.52 on Terminal-Bench 2.1, ahead of much larger US open-weight models such as Reflection Beam 501B (80.1). The weights are open under Apache 2.0 in BF16 and NVFP4, alongside a base model, and the model is also served by Together AI, GMI Cloud, OpenRouter and Fireworks.

Official source 1 ↗ · Official source 2 ↗

Features

  • Agentic coding scores. Ricursive reports 80.5 on Terminal-Bench 2.1, 76.5 on SWE-bench Verified, 61.42 on SWE-bench Pro v1.0 and 71.67 on MCP Atlas, compared in its table with Nemotron 3 Ultra 550B, Inkling 975B, Muse Spark Open 816B and Reflection Beam 501B. Official source 1 ↗ · Official source 2 ↗
  • Reasoning and math. On the same model card it scores 85.2 on GPQA Diamond and 98.3 on AIME 2025. Official source 1 ↗
  • Small dense model. A dense 65B Transformer instead of a mixture-of-experts, with a thin-and-deep shape (d_model 5120, 80 layers); Ricursive says it reaches 250 tokens per second on two B200s at batch 8 before quantization. Official source 1 ↗
  • 1M-token context. Supports up to 1M tokens of context; the reference server defaults to a 1Mi-token target context. Official source 1 ↗ · Official source 2 ↗
  • Local NVFP4 build. An NVFP4 checkpoint quantizes the MLP layers and keeps attention in BF16, aimed at running on hardware such as the NVIDIA DGX Spark. Official source 1 ↗ · Official source 2 ↗
  • Tool calls and reasoning output. The provided server accepts OpenAI-style tools and returns reasoning, the final answer and structured tool calls in separate fields. Official source 1 ↗

Pricing & free limits

Open weights

FreeDownload; Apache License 2.0, self-hosted

Instruction-tuned BF16 and NVFP4 checkpoints plus a BF16 base model on Hugging Face. Your only cost is the hardware you run it on. Official source 1 ↗

Hosted API (third-party providers)

Set by each providerUsage-based through the provider

Available on Together AI, GMI Cloud, OpenRouter and Fireworks; Ricursive's launch page does not list their prices. Official source 1 ↗

Billing details

Billing details were not established by the checked official sources.

Free access & limits

Free access and its limits were not established by the checked official sources.

Best for & limitations

Running a coding agent on an open model you host yourself, where Terminal-Bench and SWE-bench results matter. Official source 1 ↗ · Official source 2 ↗

Local development on a single NVIDIA DGX Spark with the NVFP4 checkpoint. Official source 1 ↗ · Official source 2 ↗

Agent apps that need tool calling and long context through an OpenAI-style API. Official source 1 ↗ · Official source 2 ↗
  • Preview with light post-training. Ricursive calls this a Preview whose post-training was relatively light and focused on agentic coding. Official source 1 ↗
  • Text only, mostly English. Pretraining used a text-only corpus that is predominantly English and code. Official source 1 ↗
  • Vendor-reported benchmarks. Scores come from Ricursive's own table, which mixes official model-card numbers with its in-house evals; Ricursive calls it a best-effort comparison. The $32M training cost is its own estimate. Official source 1 ↗ · Official source 2 ↗
  • Reference server needs big GPUs. The bundled server targets two NVIDIA B200 GPUs on Linux with CUDA 13, and its chat template has no thinking on/off switch or reasoning-effort levels. Official source 1 ↗
  • Strict schemas for required tool calls. For tool_choice "required", non-strict function schemas produced extra argument fields in Ricursive's validation. Official source 1 ↗
Ripple-65B Preview product screenshot
Website previewFixed desktop viewport · 1440 × 900

Similar tools

Published tools that share its categories.
ColdteaControl layer for AI-written software: map every pull request, test the flows it touches with agents and watch it in production.
Coding & DevelopmentFree planChecked Aug 23
Visit
OpenLLMA routing layer that puts your AI subscriptions, API keys and local models behind one key for Claude Code, Codex and other agents, with fallback chains.
Coding & DevelopmentFree planChecked Oct 31
Visit